
How to detect AI agents on your website
Over half the AI-agent traffic in our logs was spoofed. Check crawlers against vendor IP ranges or signatures, and judge agentic browsers on behaviour.
9 min read
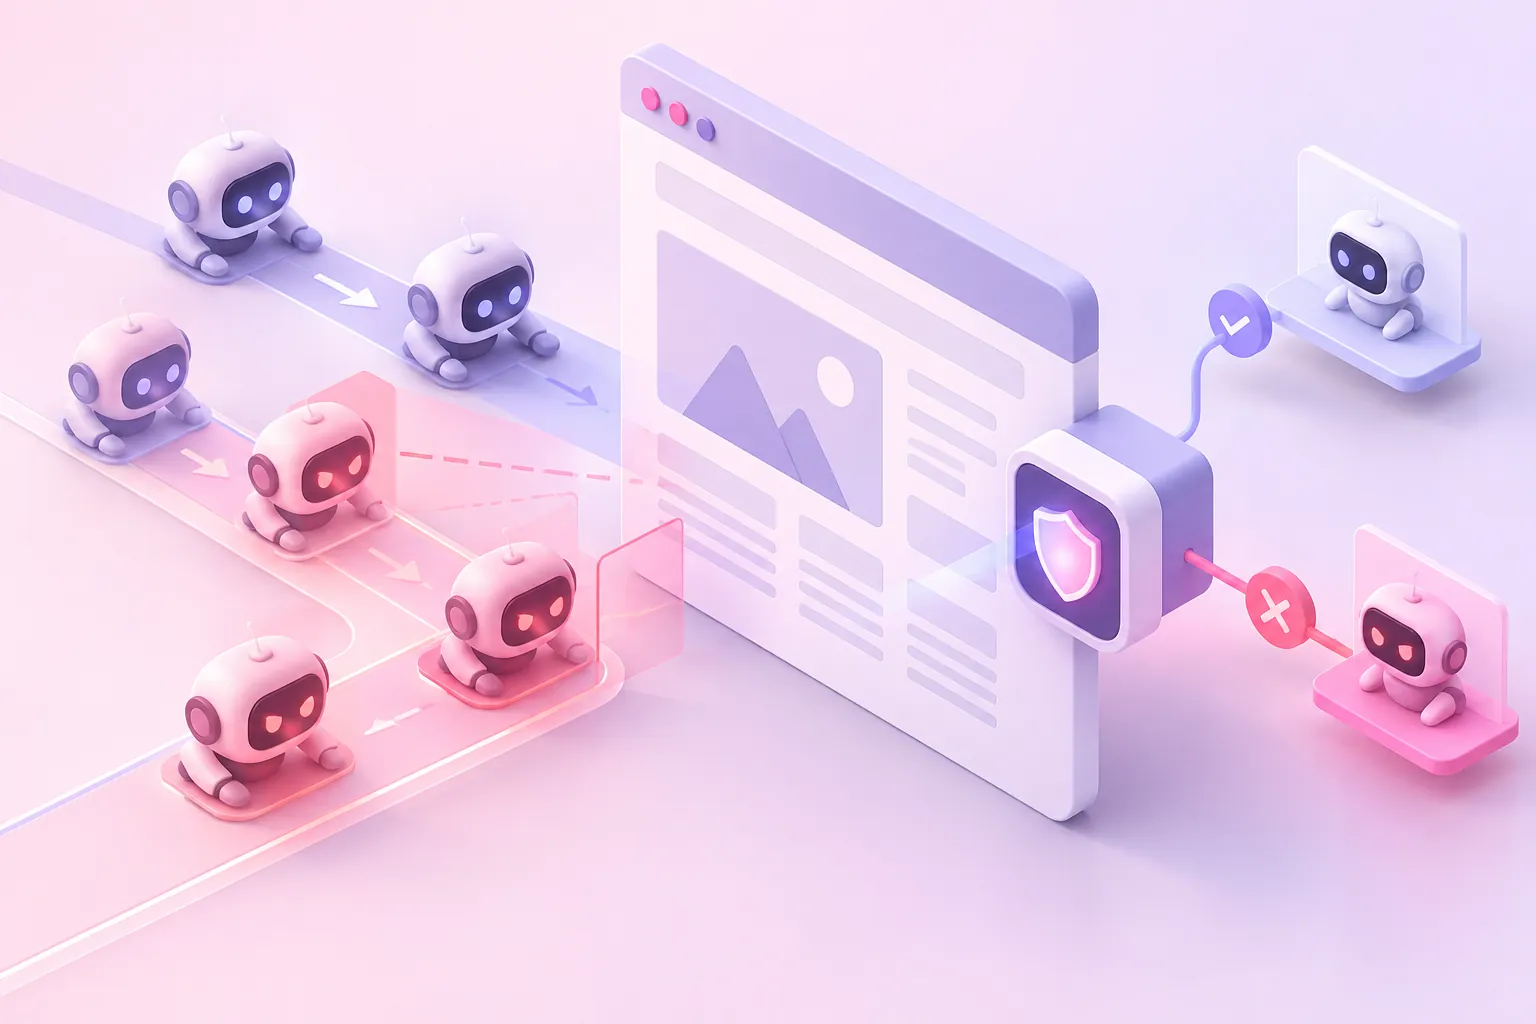
"AI agent" covers four kinds of traffic that behave differently and need different checks. Three of them declare themselves and can be verified against lists the vendors publish. The fourth, the agentic browser, runs a real Chrome on a real customer's machine and usually declares nothing at all.
The other thing to know before you start is that the name on the request is often a lie. In our own logs, more than half of the requests calling themselves AI agents were not.
Four kinds of AI agent traffic
Training crawlers collect pages that may be used to train a model. GPTBot (OpenAI) and ClaudeBot (Anthropic) are the best known. They crawl on their own schedule and respect robots.txt.
Search crawlers build the index an assistant searches when it answers a question. OAI-SearchBot (OpenAI), Claude-SearchBot (Anthropic) and PerplexityBot are examples. Blocking them keeps you out of that assistant's search results.
User-triggered fetchers visit a page because a person has just asked an assistant something that needs it. ChatGPT-User, Claude-User and Perplexity-User work this way, and so does DuckAssistBot. OpenAI and Perplexity both say that because a person started the fetch, robots.txt rules may not apply.
Agentic browsers carry out a task for a person — finding a product, filling in a form, booking something — by driving a browser. Some run in the vendor's cloud, such as ChatGPT's agent. Others run on the user's own computer, such as Perplexity Comet. We cover why they fail every classic bot test in agentic browsers.
Known AI agents and how to verify each
These are taken from each vendor's own documentation, checked on 2 November 2026.
| Agent | Operator | Purpose | How to verify |
|---|---|---|---|
GPTBot | OpenAI | Training crawler | IP ranges at openai.com/gptbot.json |
OAI-SearchBot | OpenAI | Index for ChatGPT search | IP ranges at openai.com/searchbot.json |
ChatGPT-User | OpenAI | Fetches a page when a user asks ChatGPT | IP ranges at openai.com/chatgpt-user.json |
| ChatGPT agent | OpenAI | Agentic browser running in OpenAI's cloud | HTTP Message Signatures with Signature-Agent: "https://chatgpt.com", keys at chatgpt.com/.well-known/http-message-signatures-directory |
ClaudeBot | Anthropic | Training crawler | IP ranges at claude.com/crawling/bots.json |
Claude-SearchBot | Anthropic | Index for Claude's search | Same Anthropic list |
Claude-User | Anthropic | Fetches a page when a user asks Claude | Same Anthropic list |
PerplexityBot | Perplexity | Index for Perplexity search, not training | IP ranges at perplexity.ai/perplexitybot.json |
Perplexity-User | Perplexity | Fetches a page when a user asks Perplexity | IP ranges at perplexity.ai/perplexity-user.json |
| Comet | Perplexity | Agentic browser on the user's own machine | None. It reports an ordinary Chrome user-agent |
DuckAssistBot | DuckDuckGo | Fetches pages for DuckAssist answers, not training | IP ranges at duckduckgo.com/duckassistbot.json |
Google-Extended | A robots.txt token controlling Gemini training use | None needed. Google says it has no user-agent of its own, so any request carrying it is fake |
Sources: OpenAI's crawler documentation, OpenAI's agent allowlisting guide, Anthropic's crawler documentation, Perplexity's crawler documentation, DuckDuckGo's DuckAssistBot page and Google's crawler list. On Comet, both 4sysops and the MIT AI Agent Index report that it uses the same user-agent as Chrome, and Perplexity does not document one.
More than half the AI user-agents in our logs were spoofed
Between 5 and 18 October 2026, prosopo.io received 17,935 requests carrying an AI user-agent. 53% of them came from IP addresses that did not belong to the vendor named.
Most of the impostors were on Google Cloud. Single addresses presented 11 to 13 different AI user-agents each and used them to probe paths such as /.env and /actuator, which is somebody looking for leaked credentials and exposed admin endpoints, not an assistant reading a blog post. An AI name is a cheap disguise on any site that lets AI agents through on the user-agent alone.
For some vendors there was no genuine traffic at all. Every request presenting an xAI, Cohere, Mistral or Google-Extended user-agent came from a spoofer. Google-Extended is the clearest case, because Google never sends it as a user-agent.
The genuine traffic is real and worth having. Between 19 October and 1 November 2026, verified answer-time fetches by AI assistants averaged 248 a day. Those are the requests that put your pages into an assistant's answer, which is why blocking on the user-agent alone costs you something whichever way you get it wrong.
Four ways to identify an AI agent
User-agent string. This is fine for sorting traffic you have already verified, and for writing robots.txt rules, but never treat it as proof, and never block on its absence, because anyone who does not want to be noticed stops sending it.
Published IP ranges. This is the most useful check available today. Match the source address against the vendor's JSON file from the table above, and refresh the files regularly because they change: OpenAI's ChatGPT-User list was regenerated on 27 October 2026 and Perplexity's on 28 October. A request claiming to be GPTBot from an address outside gptbot.json is not GPTBot.
Reverse DNS. Look up the hostname for the source IP, check it belongs to the vendor's domain, then look that hostname up again and check it returns the same IP. Google documents this for its crawlers, whose hostnames end in googlebot.com, in its guide to verifying Google's crawlers. Not every AI vendor supports it, so use the IP files where they exist.
Request signatures. With Web Bot Auth, an agent signs each request using HTTP Message Signatures (RFC 9421), and you check the signature against a key directory the operator publishes. OpenAI's agent already does this. A signature travels with the request wherever it comes from, so it keeps working when an IP list goes stale. It tells you which agent sent the request but not whether you want it to do what it is doing, which we cover in AI agent identity.
Detecting agentic browsers with behaviour and network signals
An agentic browser running on the user's own computer has no IP range to check and often no signature. It is real Chromium on real hardware, on a home connection, carrying the user's cookies.
Checks for automation tools inside the browser are not a durable answer. Commercial anti-detect browsers patch Chromium at the C++ level, so anything visible to JavaScript can be removed or faked. Signals rooted in hardware and the network are harder to change:
- The connection. The TLS handshake (summarised as a JA4 fingerprint) and the TCP behaviour of the connection show what really opened it. If the browser says Windows and the TCP stack is Linux, or the connection arrives through a proxy tunnel, the claim does not hold up.
- The address. IP reputation, the network the address belongs to, and whether it is a known residential proxy exit. A cloud-hosted agent arrives from a data centre, and an impostor rotating through a proxy pool shows up as many addresses sharing one pattern.
- Timing. A person pauses, re-reads and gets distracted, but an agent acts at an even rhythm, and its input lacks the small irregularities of a hand on a mouse or a finger on glass.
- Volume and spread. One customer's agent is one session doing one task. Hundreds of sessions with the same pattern across rotating addresses is an operator using agent tooling at scale.
Blocking, allowing, or requiring a human on specific steps
Once you can tell the kinds apart, the policy is a business decision rather than a technical one.
Block impostors outright. A request with an AI user-agent from an address the vendor does not publish is lying about who it is, and nothing is lost by refusing it.
Decide training crawlers on their own terms. If you do not want your content used for training, say so in robots.txt and enforce it by IP for the crawlers that publish ranges.
Let search and answer-time fetchers through. They are how assistants find and cite you. In our llms.txt experiment, IP-verified AI crawlers fetched robots.txt about 170 times as often as llms.txt, so the effort belongs in the pages themselves.
Require evidence of a human on the steps that cost you money. Let any agent browse, search and compare, and ask for a person at checkout on limited stock, account signup, password changes and bulk export. The customer who delegated the task finishes that step themselves, and a scalper or scraper is restricted in the same place whatever tool they are using. If you expose tools to agents directly, the same thinking applies to MCP servers.
Prosopo Protect runs at your edge on Cloudflare Workers or AWS Lambda@Edge and checks every request. Access Rules match on IP range, ASN, user-agent, JA4 fingerprint and IP category, so a rule can refuse AI user-agents arriving from data-centre addresses that are not the vendor's. Network checks compare the TCP connection with the device the browser claims to be, and every block names the detector that fired, so when a real customer's agent is stopped you can tell them why.
Not sure which AI agents are really reaching you?
A Bot Exposure Assessment is a 30-minute call with an engineer. We look at your traffic, show where your current setup leaves gaps, and agree how a trial would be judged. Nothing to install first.
Questions
Something else? Ask an engineer.
How do I detect AI agents on my website?
Sort them into four kinds first: training crawlers such as GPTBot and ClaudeBot, search crawlers such as OAI-SearchBot and PerplexityBot, fetchers a person triggers by asking an assistant a question, such as ChatGPT-User, Claude-User and Perplexity-User, and agentic browsers that drive a real Chrome for a person. The first three declare themselves in the user-agent and can be checked against IP ranges the vendor publishes. Agentic browsers usually look like ordinary Chrome, so you identify them by request signatures where the vendor sends them, and otherwise by behaviour, timing and network signals.
Can I trust the user-agent to identify AI bots?
No. In our own logs, 53% of 17,935 requests to prosopo.io carrying an AI user-agent between 5 and 18 October 2026 came from addresses that did not belong to the vendor named. A user-agent is useful for allowing traffic you have already verified another way, and useless for deciding what to block.
How do I verify that a request really comes from OpenAI, Anthropic or Perplexity?
Check the source IP against the vendor's published range file. OpenAI publishes openai.com/gptbot.json, openai.com/searchbot.json and openai.com/chatgpt-user.json. Anthropic publishes claude.com/crawling/bots.json. Perplexity publishes perplexity.ai/perplexitybot.json and perplexity.ai/perplexity-user.json, and DuckDuckGo publishes duckduckgo.com/duckassistbot.json. Google's crawlers can be checked by reverse DNS or against Google's own range files. ChatGPT's agent signs its requests, so you can check the signature instead.
How do I detect an agentic browser such as Perplexity Comet?
Not by its user-agent, because Comet reports itself as ordinary Chrome and runs on the user's own machine and connection. Useful signals are the ones that come from hardware and the network rather than the JavaScript environment: whether the TLS and TCP behaviour matches the device the browser claims to be, the reputation of the address, input timing that is too even to be a hand, and how many sessions share the same pattern.
What is ai agent traffic and how much of it is there?
It is any request made by an AI system rather than a person at a keyboard: crawlers gathering training data, search indexers, fetches made while an assistant answers a question, and agentic browsers carrying out tasks. On prosopo.io between 19 October and 1 November 2026, verified answer-time fetches by AI assistants averaged 248 a day.
Should I block AI agents?
Block the impostors and decide on the rest flow by flow. Training crawlers can be refused in robots.txt and enforced by IP. Search and answer-time fetchers are how assistants find and cite you, so blocking them removes you from the answers. Agentic browsers are often customers. The useful policy is to let agents read freely and require evidence of a human on the steps that cost you money, such as checkout and signup.
Related reading
 Agentic browsers: your customer is now a robot, and that is fine An agentic browser is automation operated by a real customer. It fails every classic bot test and still deserves to reach your checkout. The answer is to require evidence of a human on particular steps, rather than to judge the client.
 Perplexity Comet: what an agentic browser does to your site, and the court case about it Comet is free on every platform and its agent acts on sites for a real user. Amazon sued over exactly that, won an injunction, then lost it on appeal. The access question is now a live legal one.
 ChatGPT Atlas has been discontinued: what replaced it and what it means for your site OpenAI switched Atlas off on 9 August 2026, 292 days after launch. The browser is gone, the agentic traffic is not, and the replacements reach your site from different places.
 llms.txt: AI crawlers read robots.txt 170 times as often We have published an llms.txt since May 2026. Over twelve days of IP-verified logs, AI crawlers fetched our robots.txt 511 times and llms.txt three times.
 Web Bot Auth: signed agents solve identity, not intent Web Bot Auth lets an AI agent cryptographically sign its requests so you can verify who it is. That fixes user-agent spoofing and leaves the harder question untouched: a verified agent can still be doing something you do not want.
 x402 and agent payments: what a machine-payable endpoint means for your site x402 revives HTTP 402 so an agent can pay for a request in stablecoins and retry it. That turns abuse into a priced transaction, and it does not decide who is allowed to buy.